Scality Launches AI Inference Factory for On-Premises Deployment
News related to:Scality · 2 min read
SAN FRANCISCO, Oct. 08, 2026 /CourierPR/ -- Scality, a global leader in data infrastructure software for AI storage at scale, has launched a new solution called AI Inference Factory. This software stack enables enterprises, government agencies, and neo-cloud providers to deploy and operate AI inference on their own infrastructure, offering a supported alternative to cloud-based AI services.
AI Inference Factory addresses the challenges faced by organizations scaling AI in production. These challenges include unpredictable costs, changes in model versions and quantization, and sovereignty concerns over data processing. The solution allows organizations to run critical AI processes on-premises, providing greater control over model lifecycles and data sovereignty.
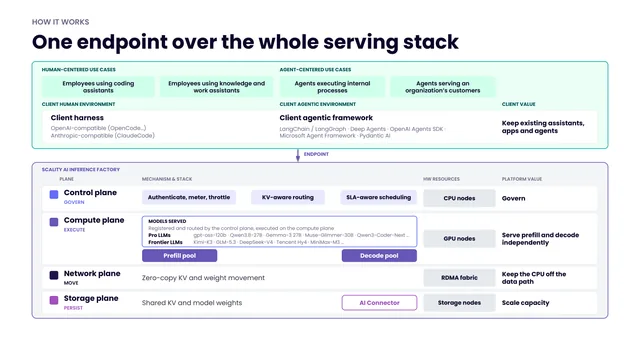
The AI Inference Factory combines validated open-weight models, a disaggregated inference-serving layer, a control plane for authentication, metering, routing, and scheduling, and Scality AI Data Infrastructure (ADI). ADI uses policy-governed autonomous operations to manage massive datasets across the AI lifecycle. Scality validates, ships, and maintains the integrated stack, helping organizations keep pace with rapidly changing models, serving technologies, and security requirements.
Scality ADI extends AI inference beyond GPU memory constraints by providing a shared, multi-petabyte cache. This cache allows inference infrastructure to preserve and retrieve model context, improving GPU utilization and reducing inference costs. Scality testing demonstrated that ADI can reduce GPU consumption while maintaining the same level of performance. For example, a 1.9-second load time for Gemma-3 27B was achieved, almost 10x faster than local NVMe, with the model streamed in parallel across the cluster over RDMA. Additionally, a 166 ms warm time-to-first-token on a 14K-token context restore from ADI was recorded, only 83 ms behind HBM.
The architecture separates prefill from decode, with ADI acting as the shared cache between GPU pools. This allows available decode GPUs to access existing context without tying it to a specific GPU server. Scality ADI provides a shared, multi-petabyte cache that GPUs read at latency the same order of magnitude as GPU memory, allowing them to retrieve existing context and remain focused on inference.
Scality AI Inference Factory is designed to preserve customer choice across the AI infrastructure stack. It is compatible with open-source harnesses and agentic frameworks such as OpenCode, Hermes, Goose, LangGraph, and Pydantic AI, and runs validated open-weight models such as Mistral, Gemma, gpt-oss, Qwen, Kimi, GLM, and DeepSeek. The software deploys on standard servers from Dell, HPE, Lenovo, and Supermicro. Every software component Scality ships is delivered as open code, enabling customers to inspect how inference state is stored and moved.